
By Kimia Majd, Zhuoran Yang
Publication Date: 2026-10-23 20:47:00
As AI agents become more capable and their use expands across cybersecurity and other domains, the need for effective evaluation grows. An agent investigating a codebase makes a sequence of decisions: where to look, which tools to use, how to interpret the evidence, and when to submit a finding. Evaluating that work requires clear task definitions, consistent execution conditions, and a way to examine both the process and the outcome.
We’re introducing Agentic FAITH, an extension of Cisco Foundation AI’s FAITH evaluation framework. It brings tasks that require multiple steps and tool use into the same framework teams already use for question-answering benchmarks. Researchers and engineers can now use one workflow to run cybersecurity evaluations, grade outcomes, and analyze results across both kinds of tasks.
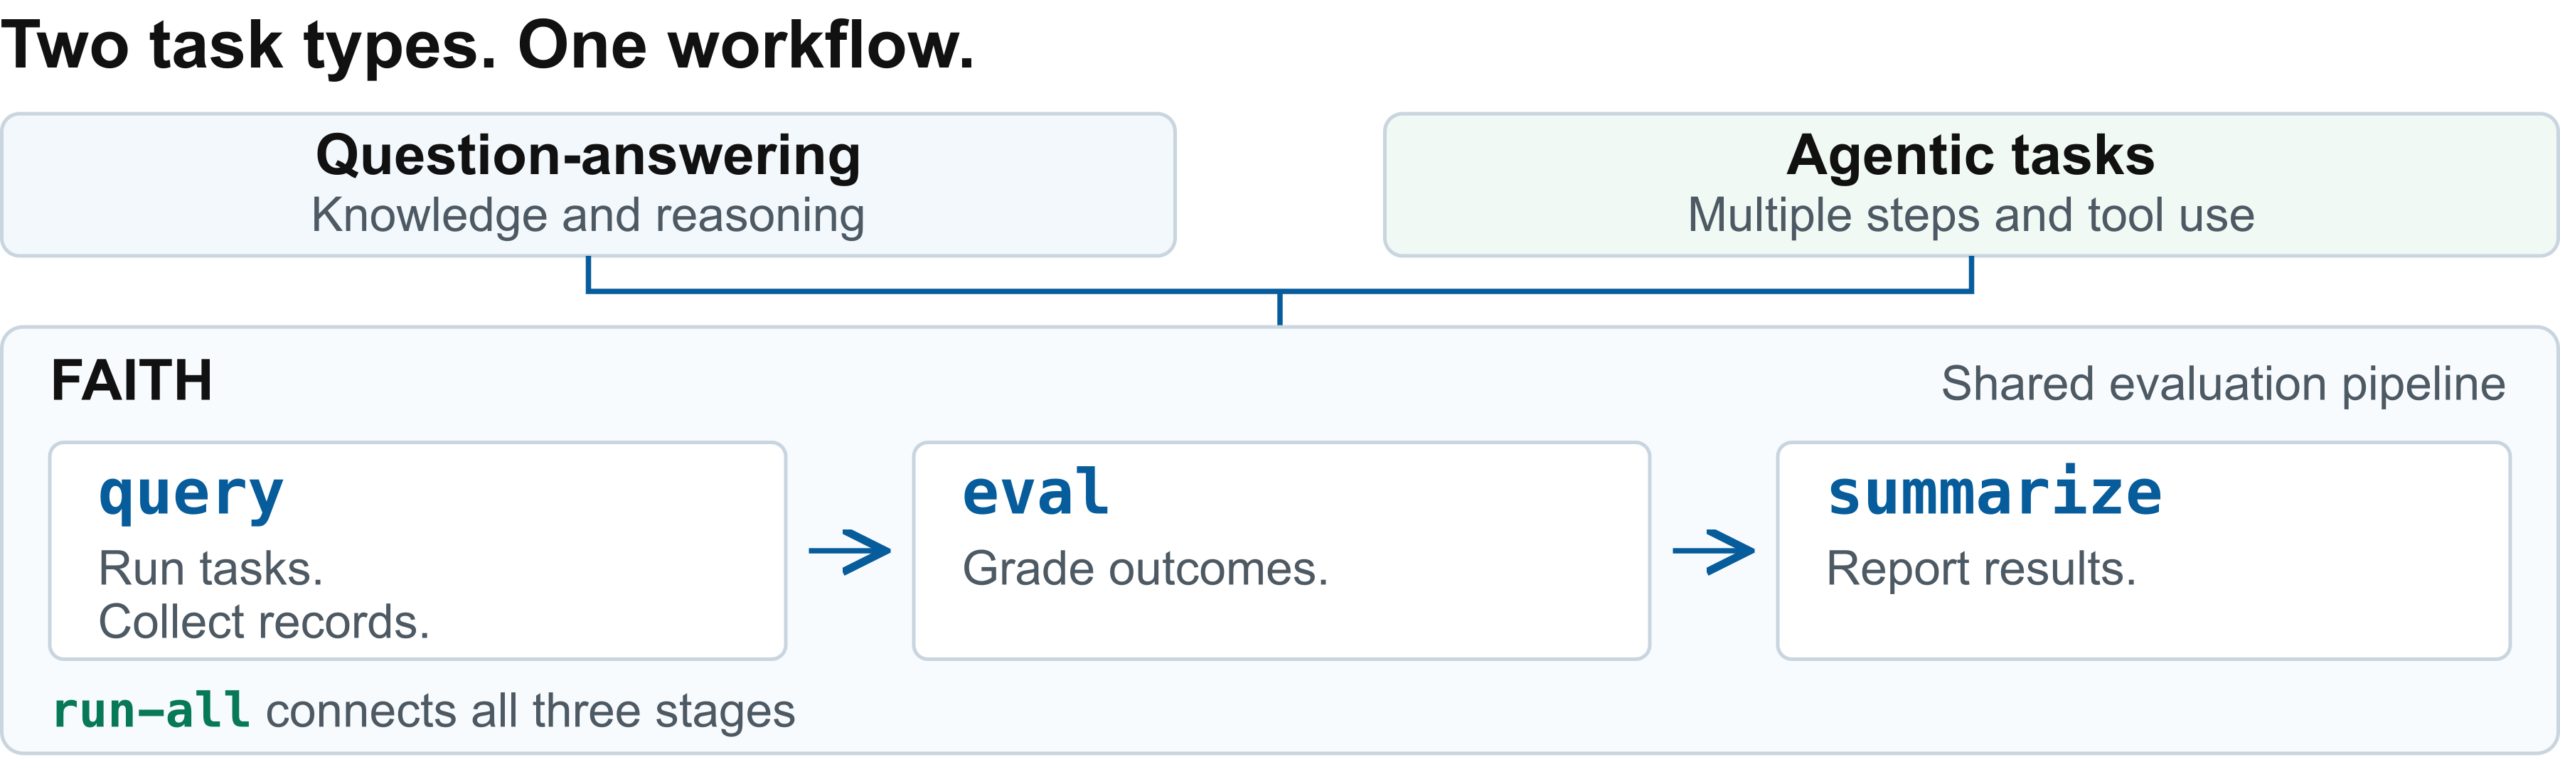 Figure 1. Traditional and agentic benchmarks share a workflow, with each benchmark defining its own tasks and scoring.

